- Date
Autoblogging: How to Automate Content Responsibly
 Andrii Romasiun
Autoblogging uses software to automate parts of a content workflow, spanning topic discovery, drafting, formatting, scheduling, and distribution. Automation is a workflow choice rather than an automatic ranking strategy, meaning success depends on whether those published pages attract the right readers and produce measurable outcomes. Counting raw URL output reveals little about quality. You need to know if those pages serve a legitimate purpose, which requires a reliable measurement layer. Swetrix connects privacy-conscious tracking with the technical insights required to run an automated content operation safely.
Which Publishing Steps Software Can Automate
Publishing requires dozens of repetitive tasks before an article reaches a reader. Software handles keyword clustering, source material gathering, and basic outline generation. An automated pipeline can also write image alt text, assign taxonomy tags, and push a formatted draft into your content management system. Delegating mechanical formatting frees writers and editors to focus on adding original insight and verifying claims.
The Main Autoblogging Models
Different tools target different parts of the publishing pipeline. The chosen model determines the level of quality control required before publication.
- Feed or RSS autoblogging: This method imports headlines, excerpts, or full articles from external feeds, creating a risk of publishing duplicate or lightly rewritten content that offers little unique value.
- AI-assisted blogging: Writers use artificial intelligence for research support, outlining, section drafting, and metadata creation. Factual errors, generic prose, and unsupported claims remain the primary risks here.
- First-party content automation: You can turn internal data, release notes, or structured records into published pages. This approach risks creating thin pages if individual URLs fail to add unique value to the broader site.
- Human-in-the-loop publishing: Software automates repetitive steps while a human editor reviews and approves the content before publication. The process moves slower than full automation, yet it aligns much better with brand standards and quality control.
- Fully automated publishing: A system selects topics, generates pages, and publishes them without review. The resulting output carries a high risk of degraded quality, rights violations, and erosion of brand trust.
How the Autoblogging Pipeline Works
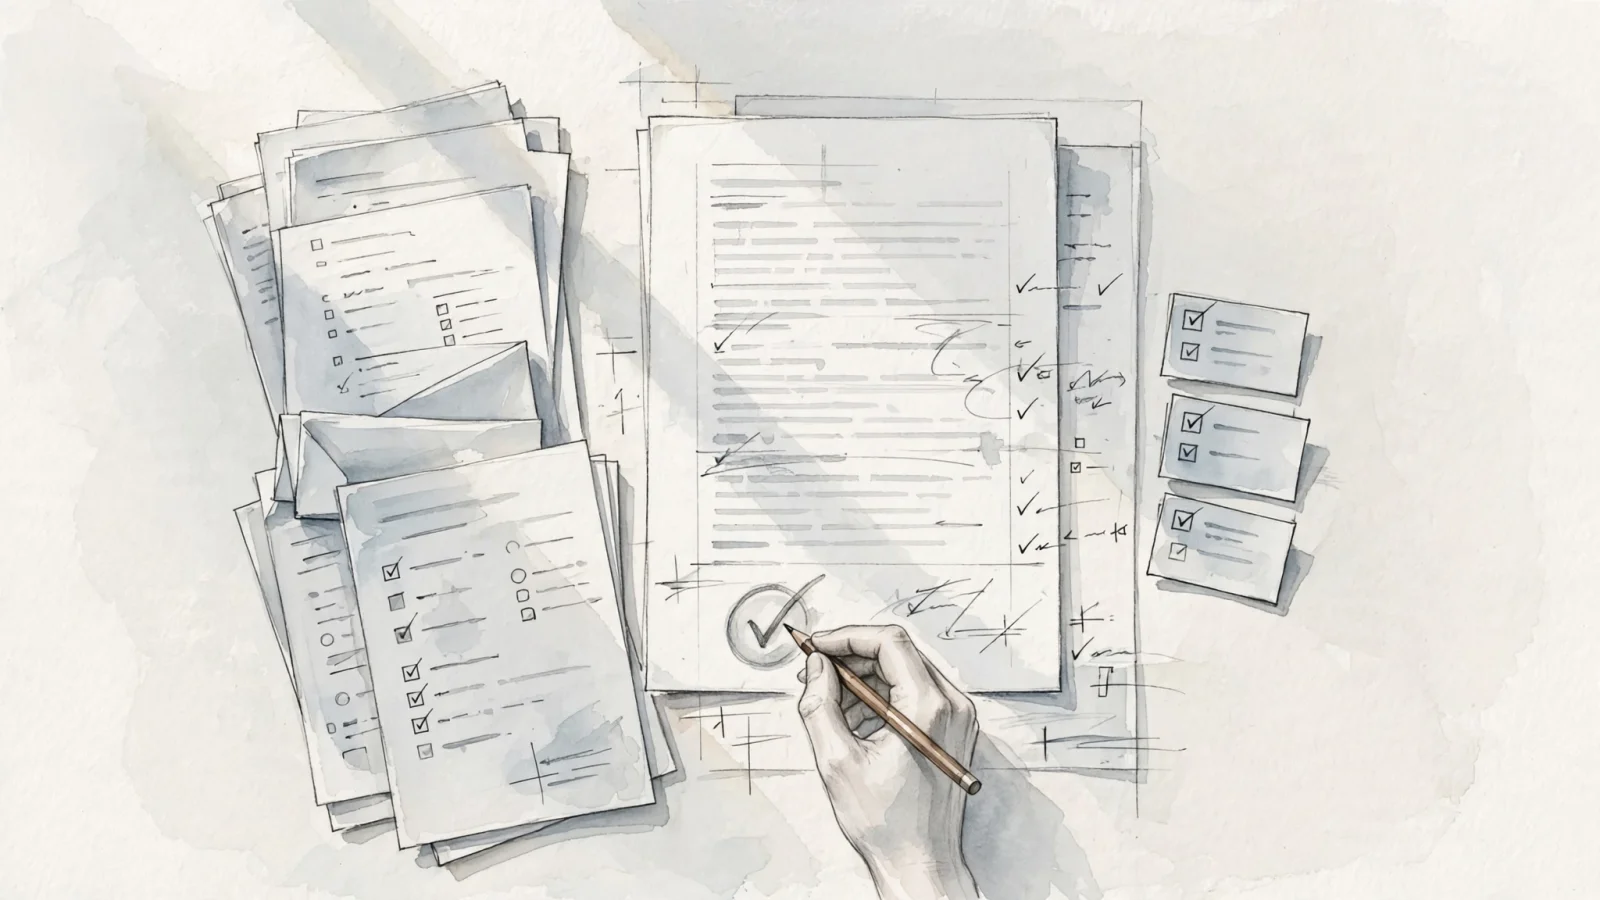
A structured autoblogging pipeline moves raw information through defined stages. A publishing connector pushes content through a queue, yet it cannot reliably verify claims or decide if a page deserves indexing.
From Topic Discovery to Draft
The process begins by selecting a topic or a first-party content source before the system gathers relevant data points. Based on predefined templates or prompts, the software assembles a draft. A human writer then enters the workflow to add original analysis, practical examples, or first-hand experience. An automated first-party release-note workflow provides a positive example of this structure: software formats structured changelog data into a readable page before a developer adds a summary explaining the update. This approach provides direct value, unlike lightly rewritten external news feeds.
From Review to Publication
Once the draft takes shape, editorial review begins. A human verifies claims, checks source links, confirms media rights, and ensures the text matches the brand voice. The software then takes over again to format the page, suggest metadata, and recommend internal links. Finally, the system sends the article for approval or publishes it directly through a content management system like WordPress.
The Post-Publication Feedback Loop
Publishing the page initiates the distribution phase, sending the link to social channels or email newsletters. You then monitor search visibility, behavior metrics, and conversion rates to determine the next action. Based on that performance data, you might update the content, consolidate it with related posts, set up redirects, or remove the page entirely to maintain site quality.
Autoblogging vs. AI Blogging, Programmatic SEO, and RSS
These terms frequently overlap in marketing materials, making it helpful to understand exactly what a specific tool automates.
| Approach | What It Automates | Typical Input | Main Quality Risk |
|---|---|---|---|
| AI Blogging | Research, drafting, editing, metadata creation | Prompts, source documents, keyword lists | Factual errors, generic unoriginal prose |
| Autoblogging | The broader publishing pipeline (scheduling, CMS integration) | Drafts, feeds, structured data | Loss of editorial and brand control |
| Programmatic SEO | Generating pages at scale from templates | Structured databases, internal datasets | Thin pages lacking unique value |
| RSS Aggregation | Importing content from external websites | External XML/RSS feeds | Duplicate or scraped content |
AI Blogging and Autoblogging
AI blogging usually means using artificial intelligence to research, outline, draft, or edit text, while autoblogging covers the broader publishing pipeline. An automated pipeline might avoid AI entirely, choosing instead to format, schedule, and publish human-written text.
Programmatic SEO and First-Party Data
Programmatic SEO generates pages from templates and structured data at scale. This tactic proves useful when every page serves a clear purpose and contains meaningful unique value. A real estate site generating neighborhood statistics pages from a proprietary database benefits readers, whereas generating thousands of local service pages by swapping city names into identical text offers no real utility.
RSS Aggregation and Republishing
RSS aggregation supports monitoring or topic discovery for human editorial teams. Automatically republishing that feed content directly to a public blog creates severe quality issues, especially without original commentary or unique analysis. Because none of these approaches replace editorial judgment, prioritizing source controls, approval gates, CMS integration, and reliable measurement will protect your site.
How Autoblogging Interacts With SEO
Autoblogging itself does not inherently damage search engine optimization. The policy risks emerge from automated pages that are unoriginal, thin, scraped, or created primarily to manipulate rankings. Search engines evaluate the quality of the output rather than the exact method of creation.
What Google Allows
Google's guidance says generative AI can help with research and add structure to original content. The company's guidance on generative AI focuses on accuracy, quality, and relevance, including when content is automatically generated. That guidance says generating many pages without adding value for users can violate its scaled content abuse policy.
What Creates Scaled-Content Abuse
Generating many pages primarily to manipulate search rankings, without adding meaningful value for users, is Google's definition of scaled content abuse under its spam policies for web search. Those policies warn against low-value feed scraping, stitched text, and using AI to generate many pages without adding value. They also list synonymizing scraped material where little value is provided and stitching or combining content from different pages without adding value as examples of scaled content abuse. To assess the value such content provides, Google's people-first content principles ask creators to consider original information, research or analysis, first-hand expertise, and a substantial, complete, or comprehensive description of the topic.
Technical SEO Does Not Guarantee Indexing
Technical SEO makes a page eligible for crawling, yet it cannot guarantee indexing, ranking, or inclusion in specific search features. A perfectly structured automated site will struggle to index if the pages provide no distinct benefit to readers. The crawler follows available links and evaluates the technical foundation, while the indexing system decides if the content warrants storage based on quality.
Building a Responsible Human-in-the-Loop Workflow
A practical workflow automates repetitive tasks without delegating editorial responsibility. This approach maintains control over the final product while accelerating the mechanical steps of publishing.
Automate the Repetitive Layer
Software safely automates topic clustering, content briefs, basic outlines, and HTML formatting. These tools handle metadata suggestions, internal-link recommendations, image resizing, and alt-text drafting efficiently. Scheduling, UTM parameter generation, performance reporting, and carefully scoped first-party documentation updates also serve as excellent candidates for full automation.
Keep Editorial Ownership
Human ownership remains necessary for judging audience fit, source quality, and factual accuracy. Editors verify originality, conduct actual product testing, and authorize affiliate recommendations. That means image rights, excerpt licenses, indexability decisions, and final publication approvals belong to human editors.
Apply Risk Tiers and a Pre-Publication Gate
Different types of content require different levels of oversight.
- Formatting and metadata: Use automation with periodic spot checks.
- Evergreen explainers: Generate an AI-assisted draft, following up with detailed human review.
- Product comparisons and affiliate pages: Incorporate human research, hands-on testing, formal disclosures, and manual approval.
- Breaking news: Mandate human verification immediately before publication to prevent rapid misinformation spread.
- Medical, financial, legal, and safety content: Implement specialist review, avoiding full automation for these sensitive topics.
- First-party structured pages: Automate this content only when every resulting URL carries a clear purpose and distinct value.
Running a final pre-publication checklist prevents basic errors from reaching your audience. It covers whether the page answers a real reader need, provides accurate sources, and displays current specifications or pricing. The review should also catch copying risks, verify canonicals, test internal links, and confirm appropriate image licensing. If automation substantially shaped the article, including a concise note explaining the process and the human checks builds trust with readers. Finally, checking that your conversion tracking is active ensures you can measure the post's performance.
Measure Autoblogging Beyond Pageviews with Swetrix
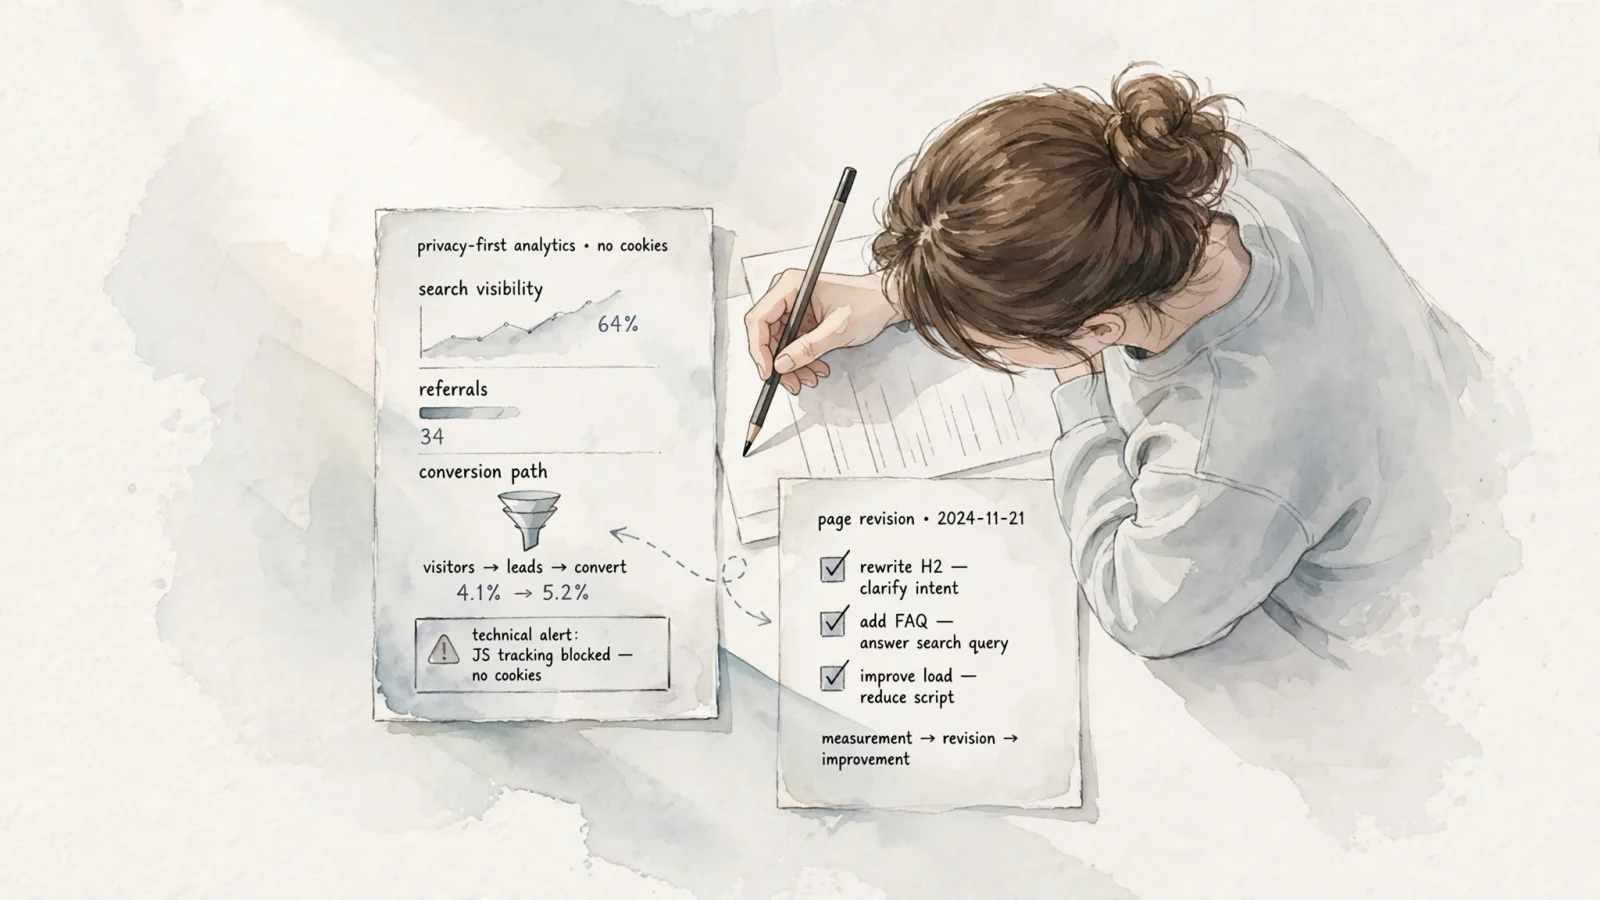
Swetrix connects lightweight, privacy-conscious traffic reporting with the deeper data needed to evaluate an automated content operation. If you need a reliable cookieless Google Analytics alternative, the platform provides the behavioral data required to validate content investments without relying on intrusive tracking banners.
Search Visibility and Acquisition
Understanding whether automated pages reach readers requires accurate search data. Connecting your Google Search Console account directly to Swetrix allows you to review queries, clicks, impressions, click-through rates, and average positions alongside your top pages. You can filter branded versus non-branded traffic while monitoring available search and AI referrals. For acquisition beyond organic search, combining browser referrers with tagged URLs offers a complete picture. Adding UTM parameters to newsletter, social media, partner, and affiliate links splits traffic clearly into organic discovery and campaign-driven visits.
Reader Journeys and Conversions
Because pageviews rarely equal revenue, measuring specific outcomes takes priority. Configuring goals and funnels within Swetrix tracks newsletter signups, file downloads, demo requests, or purchases. Revenue tracking attaches a financial value to specific content paths, all while standard analytics operate without using cookies or collecting personally identifiable information. When conversion paths break, deeper investigation becomes necessary. Swetrix provides optional session replay features, which show exactly where a reader abandons a confusing layout. Activating these replays requires deliberate configuration, masking of sensitive fields, and appropriate consent review on sensitive pages.
Technical Health and Continuous Improvement
High publishing volumes tend to amplify technical errors, making monitoring tools highly valuable. Swetrix offers specialized webmaster tools to monitor your site's technical foundation, including an on-page SEO checker to validate headings, meta descriptions, and structural tags before publication. When consolidating older automated content, a redirect validator ensures traffic flows correctly to new destinations. The platform also includes checks for sitemaps, canonicals, robots.txt files, broken links, and hreflang tags. You can even check AI search LLM crawlability to verify crawler rules alongside the emerging llms.txt convention.
Continuous improvement relies heavily on performance data. Error monitoring and A/B experiments help diagnose broken journeys or test call-to-action placements. Agencies and product teams often use the Swetrix Statistics API, public dashboards, and self-hosting options to build custom reporting environments. Ultimately, decisions to update, consolidate, or remove pages depend on qualified traffic and conversion outcomes rather than raw publication counts.
Common Questions About Automated Publishing
Is Autoblogging the Same as AI Writing?
AI writing handles text generation or editing, whereas autoblogging automates a broader workflow encompassing research, formatting, scheduling, publication, and distribution. A system can process purely human-written content by automating only the delivery pipeline.
Can AI Content Rank, and Can RSS Be Republished?
AI content can rank in search results, though search engines offer no ranking guarantees based on the creation method alone. Usefulness, accuracy, originality, technical accessibility, and a legitimate audience purpose dictate performance. RSS feeds can support monitoring and research, but automatically reproducing or lightly rewriting that feed content without adding a unique benefit creates significant spam policy risks.
How Much Human Review Does Content Automation Require?
No universal human-review percentage applies to all publishers. Increasing automation makes sense only after a workflow consistently passes accuracy, originality, rights, technical, and conversion checks. Starting with formatting and metadata lets you expand automation into research and drafting once those initial quality gates prove reliable.
Is Autoblogging Legal?
The FTC says a connection between an endorser and marketer should be disclosed clearly and conspicuously when a significant minority of consumers would not expect it and it would affect how they evaluate the endorsement.
Does Privacy-First Analytics Mean Losing Growth Data?
You can measure search visibility, qualified traffic, reader actions, conversions, revenue, errors, and page health while respecting user privacy. Invasive tracking cookies aren't necessary for determining which automated articles generate newsletter signups or product demos.
Automate the publishing workflow rather than the insight. Connecting Google Search Console to Swetrix measures search visibility, referral sources, reader journeys, conversions, and technical issues in a single privacy-first dashboard. Visit Swetrix to build an analytics foundation that scales safely alongside your automated content.