- Date
Validate Sitemap XML Before You Submit
 Andrii Romasiun
A clean syntax check does not mean search engines will index your pages. When you validate sitemap XML files, a successful parse confirms correct syntax, but it reveals nothing about whether the listed URLs are live, whether they are the canonical versions you want ranking, or whether a search crawler is permitted to access them.
Validation covers three distinct layers. First, the document must contain well-formed XML with properly nested tags and escaped characters. Second, it must comply with the Sitemap protocol, which dictates specific namespaces and required elements. Finally, the published file and its enclosed URLs must be accessible and appropriate for search engines to crawl. Completing these three checks before submitting your file to Google Search Console helps you catch issues that could waste crawl budget or lead to persistent errors in your reporting.
As you prepare your technical foundation for search crawlers, you will also need to measure how human visitors interact with those pages. While Search Console tracks your crawling and indexing status, Swetrix provides post-click visibility. Our cookieless analytics platform helps you understand traffic sources, map user journeys, and review session replays without deploying intrusive cookie banners.
Before You Start: Find the Published Sitemap
Before opening any testing tools, you need to locate the exact file your server deploys to the public. Testing a local draft file leaves you blind to server-side configuration issues, so you must test the deployed URL that search engines will request.
Many content management systems generate and update this file automatically. Do not assume the filename is sitemap.xml located at your domain root; instead, check your CMS settings to find the published path. Alternatively, open your robots.txt file and look for a Sitemap: directive near the bottom, which points directly to the active location.
Once you have the URL, load it in an incognito browser window to confirm the file loads publicly without requiring a login, returning a 404 missing-file error, or triggering a security challenge.
The location of this file determines its URL scope. A sitemap placed at the site root can include any URL on that domain. A file placed in a subdirectory, such as https://example.com/blog/sitemap.xml, can include URLs located within the /blog/ directory. If you submit a narrowly scoped file through Search Console, Google might process URLs outside that directory, but files discovered through robots.txt strictly follow this scope limitation.
Step 1: Check XML Syntax and Sitemap Rules
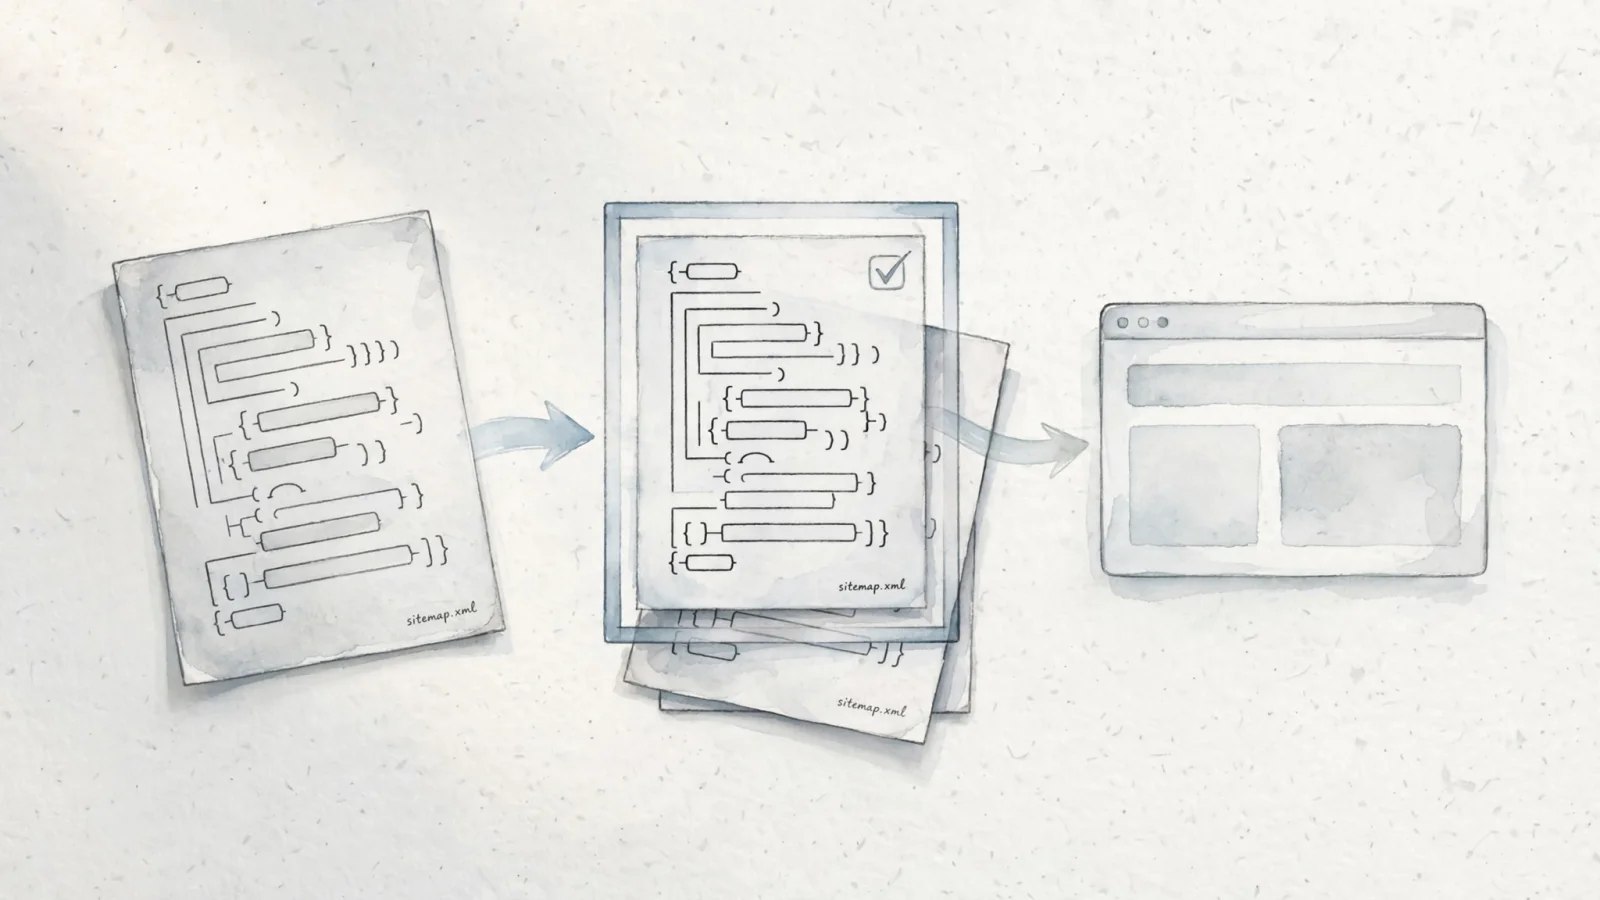
A generic XML parser verifies that your document follows basic syntax rules. According to the Extensible Markup Language (XML) 1.0 specification, well-formed XML requires a single root element, correctly nested tags, and properly escaped reserved characters. A sitemap-aware validator or a schema check goes further by applying the specific requirements of the Sitemap protocol, though neither check confirms that your pages are indexable.
For a file to pass both structural checks, it needs specific declarations and tags. A minimal, valid configuration requires a UTF-8 encoding declaration, a urlset root element referencing the correct namespace, and individual url blocks containing absolute loc paths.
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://example.com/blog/a-post/</loc>
    <lastmod>2026-10-04</lastmod>
  </url>
</urlset>
Every loc element must contain an absolute URL, meaning it includes the protocol and the exact hostname. Relative paths violate the Sitemap protocol, even if an XML parser can read them.
The XML standard reserves specific characters that break the parser if left unescaped. You must use entity escaping for data values, which most commonly affects URLs with query parameters. An ampersand in a URL must be written as & in the XML text. The less common reserved characters, such as <, also need escaping in text, while quotes and apostrophes generally do not need escaping outside attribute values. Include query-string URLs when they represent canonical pages that you want search engines to rank.
Monitor file limits and metadata formatting
A single file cannot grow indefinitely. Current documentation from Google Search Central states that a single sitemap file can contain at most 50,000 URLs and must be no larger than 50 MB uncompressed. When your sitemap exceeds either limit, you must split it into multiple smaller sitemaps, but you can optionally create a sitemap index file and submit that single index file to Google.
The Sitemap protocol supports optional metadata tags, but Google ignores <changefreq> and <priority>. You can omit them to reduce file size and bandwidth consumption.
The <lastmod> tag remains useful, provided you use it accurately. Google uses this date to determine whether a page has changed since the last crawl, so the timestamp must reflect a significant content update rather than a dynamic date that changes on page load. Format the date using the W3C Datetime standard, typically YYYY-MM-DD. If you choose to include a specific time, you must append a valid time zone offset.
Step 2: Audit the Listed URLs
Correct syntax ensures the parser can read your list. A structurally perfect file filled with broken links, duplicate content, and redirect chains harms your technical SEO efforts, so you need to review the specific URLs you ask search engines to evaluate.
Open your list and check the destinations. Every entry should point to the exact canonical version of a page you want indexed.
Review your list against these technical criteria:
- The URL uses the intended protocol, matching whether your site enforces HTTP or HTTPS.
- The hostname matches exactly, avoiding discrepancies between
wwwand non-wwwvariations. - The page returns a 200 OK HTTP status code when requested.
- The destination is a production page intended for public search, not a staging environment or an obsolete draft.
- The URL is not blocked by a
Disallowrule in yourrobots.txtfile. - The page HTML does not contain a
noindexmeta tag or HTTP header.
The Page indexing report documentation recommends URL Inspection for checking the index status of a specific URL, so use it to review the destination URL before listing it in your sitemap.
This technical audit prepares your site for discovery. Once search engines index these pages and human visitors begin clicking through, your analytics stack takes over. Search Console shows you the queries driving impressions, while Swetrix helps you analyze the visit. By tracking custom events and analyzing conversion funnels in an anonymized environment, Swetrix bridges the gap between search visibility and user action. Swetrix does not validate XML or report on indexing status, but it provides the behavioral data you need after the indexing process succeeds.
Remove any URLs from the file that should not be indexed. Once you have a clean list of canonical, indexable pages, you can submit it for processing.
Step 3: Submit the Sitemap and Fix Errors
After completing your syntax checks and URL audits, you can submit the live file directly to Google. This requires owner or full user permissions for the property in Search Console.
Open your property in Search Console, navigate to the Sitemaps report in the left sidebar, paste the exact URL of your deployed file, and click submit. Google will attempt to fetch the file and parse its contents, updating the status column to show whether the initial read was successful.
Even with careful preparation, server conditions or obscure formatting issues trigger errors. Search Console provides specific error messages in the report details, which you can view by clicking a row whose status isn't Success. Troubleshooting requires matching the symptom reported by Google to the underlying technical failure. Review this symptom-to-fix mapping to address the sitemap errors described in the Search Console Help documentation.
| Search Console Symptom | Practical Checks and Fixes |
|---|---|
| Couldn't fetch | Check the submitted URL for typos. Confirm the server is online and returning a 200 OK status. Ensure the file is not hidden behind a login screen or blocked by a firewall rule. Verify that your robots.txt file does not explicitly disallow Googlebot from accessing the XML file path. |
| Invalid XML or unsupported format | Check for duplicate, missing, or improperly nested tags. Confirm your root element is correct and includes the proper namespace declaration. Look for unescaped characters, particularly ampersands in query parameters. |
| Invalid URL or URL not allowed | Replace relative paths with absolute URLs. Fix misspelled schemes. Ensure the URLs fall within the permitted scope of the file's location on the server. If the file is in a subdirectory, remove URLs belonging to higher-level paths. |
| Invalid date | Correct your <lastmod> formatting. Use the YYYY-MM-DD format. If you specify a time of day, append a valid time zone indicator. Remove dates that are entirely malformed or invalid. |
| File-size error | Split the list into multiple smaller files. Ensure no single file exceeds 50,000 URLs or 50 MB uncompressed. Create a sitemap index to link the new files together, then submit the index URL to Search Console. |
| URLs blocked by robots.txt | Investigate whether your site's directives block the specific URLs listed inside the file. Resolve the conflict by either allowing the crawl or removing the blocked URLs from your list. You can use a robots txt generator to ensure your blocking rules are formatted correctly. |
Distinguish carefully between a blocked sitemap file and blocked URLs inside that file. If Googlebot cannot access the XML document itself, the fetch fails; if it fetches the document but finds that robots.txt blocks the enclosed URLs, it parses the file but refuses to crawl the destinations. Resolve the specific restriction causing the error, then return to the Sitemaps report and submit the URL again to trigger a fresh fetch.
Step 4: Interpret the Result and Follow Up
A "Success" status in the Sitemaps report represents a specific, limited achievement. It means Google fetched the file from your server, read the XML without encountering parsing errors, and queued the listed URLs for crawling.
It does not confirm that every page was crawled, nor does it guarantee indexing. The file serves as a discovery mechanism, so to verify indexing status, you must use the URL Inspection tool or the Page indexing report to see whether Google included the content in search results. You can also run an independent indexability checker to verify that your pages send the correct HTTP headers and meta tags.
Review these common follow-up scenarios to manage your indexing workflow correctly.
Does a valid XML sitemap guarantee indexing? No. Submitting a list of URLs helps Google discover your pages faster, especially if your internal linking is weak or your site is new. However, Google evaluates the quality, uniqueness, and relevance of every page before indexing it, meaning a perfectly formatted list of low-quality pages still results in exclusion from search results.
Does a sitemap need to be named sitemap.xml?
No specific filename is required. You can name the file index.xml, urls.xml, or rely on the dynamic paths generated by platforms like WordPress or Shopify. The parser cares about the file content and structure rather than the naming convention, so provide the correct path to Search Console and reference it accurately in your robots.txt file.
Do small sites need a sitemap? Search engines reliably crawl small websites through standard link navigation. Google states that a site with fewer than 500 pages likely does not need a sitemap, provided that every page is reachable by following links starting from the homepage. Treat this as a qualified rule of thumb. Creating the file requires minimal effort on modern platforms and provides a useful diagnostic baseline in Search Console even for small portfolios.
Should I keep optional tags like priority and changefreq?
Keep the <lastmod> tag, provided your CMS updates it only when the page content undergoes a meaningful change. Strip out <changefreq> and <priority> tags, as Google publicly states it ignores them. Removing these unread tags reduces your file size and simplifies your code.
Validating your XML file clears the path for search crawlers to evaluate your site architecture. By running structural checks, auditing the URL destinations, and resolving fetch errors in Search Console, you ensure your technical SEO foundation is solid.
Once search engines parse your URLs and begin sending traffic to your pages, you need a reliable way to measure user engagement without compromising privacy. Search Console shows you the queries driving impressions, but Swetrix shows you what happens next.
Swetrix is a privacy-first, cookieless alternative to Google Analytics. It provides the deep product analytics you need to optimize your site, including custom event tracking, conversion funnels, and session replays. Because it operates without tracking cookies, it can support privacy-conscious analytics under GDPR, CCPA, and PECR, and may reduce the need for intrusive consent banners depending on your setup. Ready to bridge the gap between technical search visibility and actionable user insights? Try Swetrix today.